GIGABYTE AI TOP ATOM: the 128 GB GB10 measured in detail
GIGABYTE's AI mini PC: NVIDIA GB10 chip and 128 GB of unified memory in one liter. We look at what matters for running LLMs locally : memory, bandwidth, speed, price—and who it's (or isn't) the right purchase for.
Updated on 09/10/2026
Where to buy it
The button configuration is the one offered for purchase. On mini PCs, keep some memory available for the system and check the inference engine; macOS/MLX and CUDA are not interchangeable.
Affiliate links — BestLLMfor may earn a commission from purchases at no extra cost to you, which does not influence these independently determined recommendations. As an Amazon Associate, BestLLMfor earns from qualifying purchases.
Technical specifications
- Memory128 GB unified (LPDDR5x), 121.7 GB visible to the system
- Bandwidth273 GB/s
- ComputeBlackwell GPU and 20 Arm cores; up to 1 PFLOP in FP4 with sparsity according to NVIDIA (announcement, not measured by us)
- Power consumption240 W USB-C adapter; GPU at 10.4 W at idle and averaging 39 to 53 W under load in our readings (GPU only, without a power meter)
- Indicative price6 346,27 € (ATAGB10-9001, 4 TB PCIe 4.0, official AORUS store, sold out; in stock on Amazon.fr) · 7 999,95 € (ATAGB10-9000, 4 TB PCIe 5.0, LDLC and Materiel.net, out of stock) — recorded on 08/10/2026
- Largest modelQwen3-235B-A22B in 3-bit (90.5 GB occupied, 21 GB headroom) · Llama 3.3 70B at about 5 tokens per second, 2.6 to 4 times faster with a small draft model · gpt-oss 120B at 58 tokens per second; our 13 models, from 4B to 235B, fit with a 32,768-token context
Who is it for?
Advantages and limitations
✓ Strengths
- 128 GB of unified memory: our 13 models, from 4B to 235B (in 3-bit), fit with 32,768 tokens of context
- The speeds of NVIDIA's DGX Spark, within at most 4.3% with llama.cpp and 2% with Ollama
- Stable speed under continuous load: 0.0% drift over 1 hour with 16 users, −0.6% over 2 hours with 8 users, no throttling reported
- 4 TB PCIe 5.0 SSD on the ATAGB10-9000: 13 GB/s read speed
- Full CUDA stack: llama.cpp, vLLM, TensorRT-LLM, and Unsloth worked for us
- One-liter chassis, 1.2 kg, clean front panel
✗ Limitations
- Higher price than a 128 GB Ryzen AI Max+ 395 mini-PC
- A dense 70B model runs at about 5 tokens per second, limited by the GB10 platform's memory bandwidth (273 GB/s): an MoE model or a small draft model (×2,6 to ×4) provides conversational speeds
What we measured
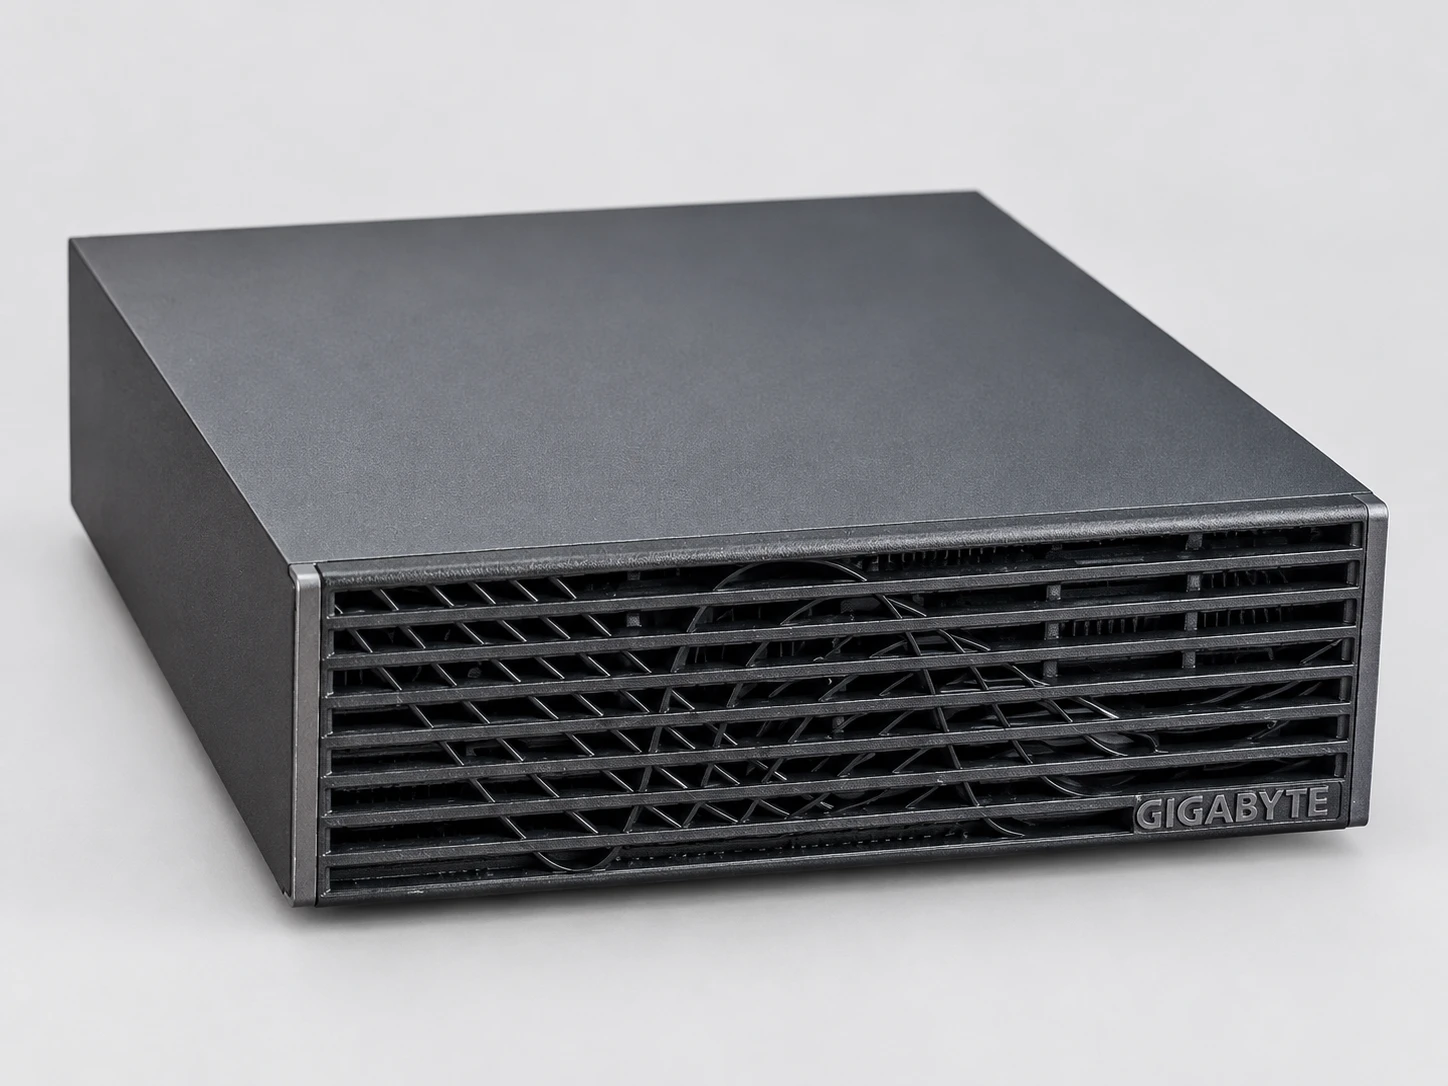
GIGABYTE provided us with an AI TOP ATOM (ATAGB10-9000: 128 GB, 4 TB PCIe 5.0 SSD) at no cost for a series of guides. The measurements and opinions are our own; GIGABYTE neither reviewed nor approved this content before publication. The methodology (protocol fixed before the first measurement), model file hashes, and data from our tables are published on our methodology page. Our data, infographics, and photos can be reused under a CC BY 4.0, citing quelllm.fr.
| Guide | What it shows |
|---|---|
| Which LLMs actually run | 13 models from 4B to 235B: all fit with 32,768 tokens of context; gpt-oss 120B at 58 tokens per second |
The series contains 7 guides, published one per week: this page grows with each new guide.
The AI TOP ATOM models
GIGABYTE offers the ATOM in six variants, from ATAGB10-9000 to ATAGB10-9005. The first three have 128 GB: 9000 with a 4 TB PCIe 5.0 SSD (the one we measured), 9001 with 4 TB over PCIe 4.0, and 9002 with 1 TB over PCIe 4.0. A 64 GB version is announced for October 23, 2026. Check the exact part number with the retailer: some product pages describe the SSD incorrectly.
Who it's for
- A team of 5 to 20 people who wants a private AI assistant for their documents (measured up to 10 simultaneous users).
- A CUDA developer who wants the complete NVIDIA stack on their desk.
- Local fine-tuning : LoRA for a Qwen3-8B, QLoRA for a 70B, and gpt-oss 120B with Unsloth.
- Large MoE models of more than 100 billion parameters, at a comfortable speed.
Verdict
Frequently asked questions
Can the GIGABYTE AI TOP ATOM run a 70B LLM locally?
Qwen3-235B-A22B in 3-bit (90.5 GB occupied, 21 GB of headroom) · Llama 3.3 70B at around 5 tokens per second, 2.6 to 4 times faster with a small draft model · gpt-oss 120B at 58 tokens per second; our 13 models, from 4B to 235B, fit with a 32,768-token context.
How much does the GIGABYTE AI TOP ATOM cost?
Count €6,346.27 (ATAGB10-9001, 4 TB PCIe 4.0, official AORUS store, sold out; in stock on Amazon.fr) · €7,999.95 (ATAGB10-9000, 4 TB PCIe 5.0, LDLC and Materiel.net, out of stock)—recorded on 08/10/2026 (64 GB version announced by NVIDIA starting at $4,999 (United States), available from 23/10/2026; GIGABYTE confirmed a 64 GB AI TOP ATOM on 05/10/2026). Prices change quickly—check the current price through the purchase links.
Who is the GIGABYTE AI TOP ATOM for?
CUDA developers, teams that want a private AI assistant, local fine-tuning, and large MoE models over 100B.
Go further
Prices in euros (€) are French market prices including VAT, checked by QuelLLM. US prices differ: the Amazon buttons show the current US price.